BACKGROUND
Cloud-based knowledge bases are convenient, but uploading private codebases and confidential scratchpads poses real privacy risks, while network latency interrupts deep flow.
APPROACH
Engineered a complete local pipeline—embedding generation, vector indexing, and local LLM inference—ensuring total privacy with sub-second response times.
HOW IT WORKS
- 01
Register
Point to local directories or repositories
- 02
Chunk
Split code and prose into semantic chunks
- 03
Embed
Generate embeddings using local models
- 04
Retrieve
Search and summarize with natural language
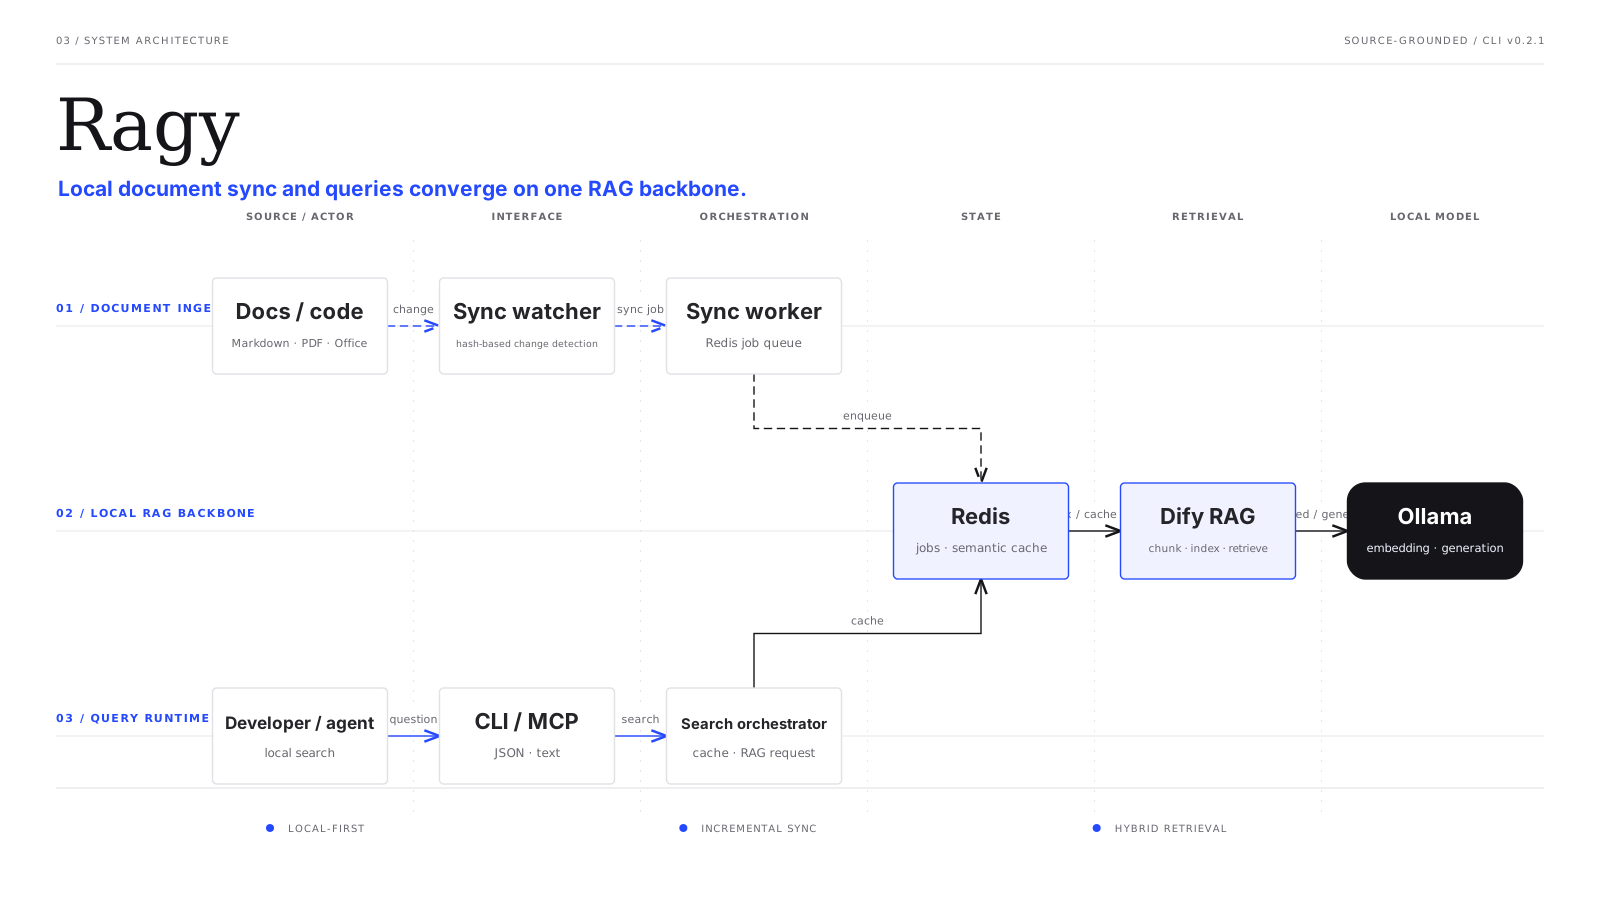
ARCHITECTURE
DESIGN DECISIONS
Hybrid BM25 + Vector Retrieval
Combines exact keyword matches (for function and variable names) with semantic vector search for optimal recall and accuracy.
Incremental Hash-Based Re-indexing
Only recalculates embeddings for modified chunks upon file saves, avoiding costly and repetitive full-corpus passes.
Unix Pipeline Friendly CLI
Built with pipeable JSON and plaintext outputs to fit naturally into scripts and terminal workflows.
VERIFICATION
- Daily usage for engineering research and internal documentation search
- Consistently maintains sub-second query latency over extensive document collections
- Verified to operate flawlessly in fully air-gapped environments
STATUS & NEXT
Actively running as a reliable background service for searching project documentation and notes.
NEXT STEPS
- Extend support to PDF and office document formats
- Dynamic chunking optimization algorithms
- Local LAN sharing mode for small teams